



There has never been a better time to build software. AI coding agents have dramatically shortened the time from "Hmm, could this work?" to actual functioning prototype. We use them every day at ScorebuddyCX. And that's why I can tell you where the line must be drawn.
This article won't argue that AI-written code is poor quality. Because it isn't, and anyone who has spent a couple of weeks with a good AI agent knows that.
The problem was never how fast code could be written. It was always what code should be written, and who is left holding it afterwards.
So the question is not to build or buy software. It's a bit more granular than that:
Do you want to become a software vendor to yourself, or buy from one that already carries the cost?
As soon as your quality assurance team starts scoring real interactions in a tool you built, you'll have taken on every obligation a vendor has, but without the economics that make those obligations sustainable in a real working environment.
We've been carrying those obligations since 2012. Everything below is what they turned out to be.
The build was never the expensive part
An agent will give you a scorecard builder, an evaluation form, an agent dashboard, and a reporting view in a matter of days. Genuinely. It's not a stretch to say you can build those features yourself.
The expensive part begins the morning after go-live and continues for as long as the business uses the tool. Suddenly, it's an obligation that you have to carry around.
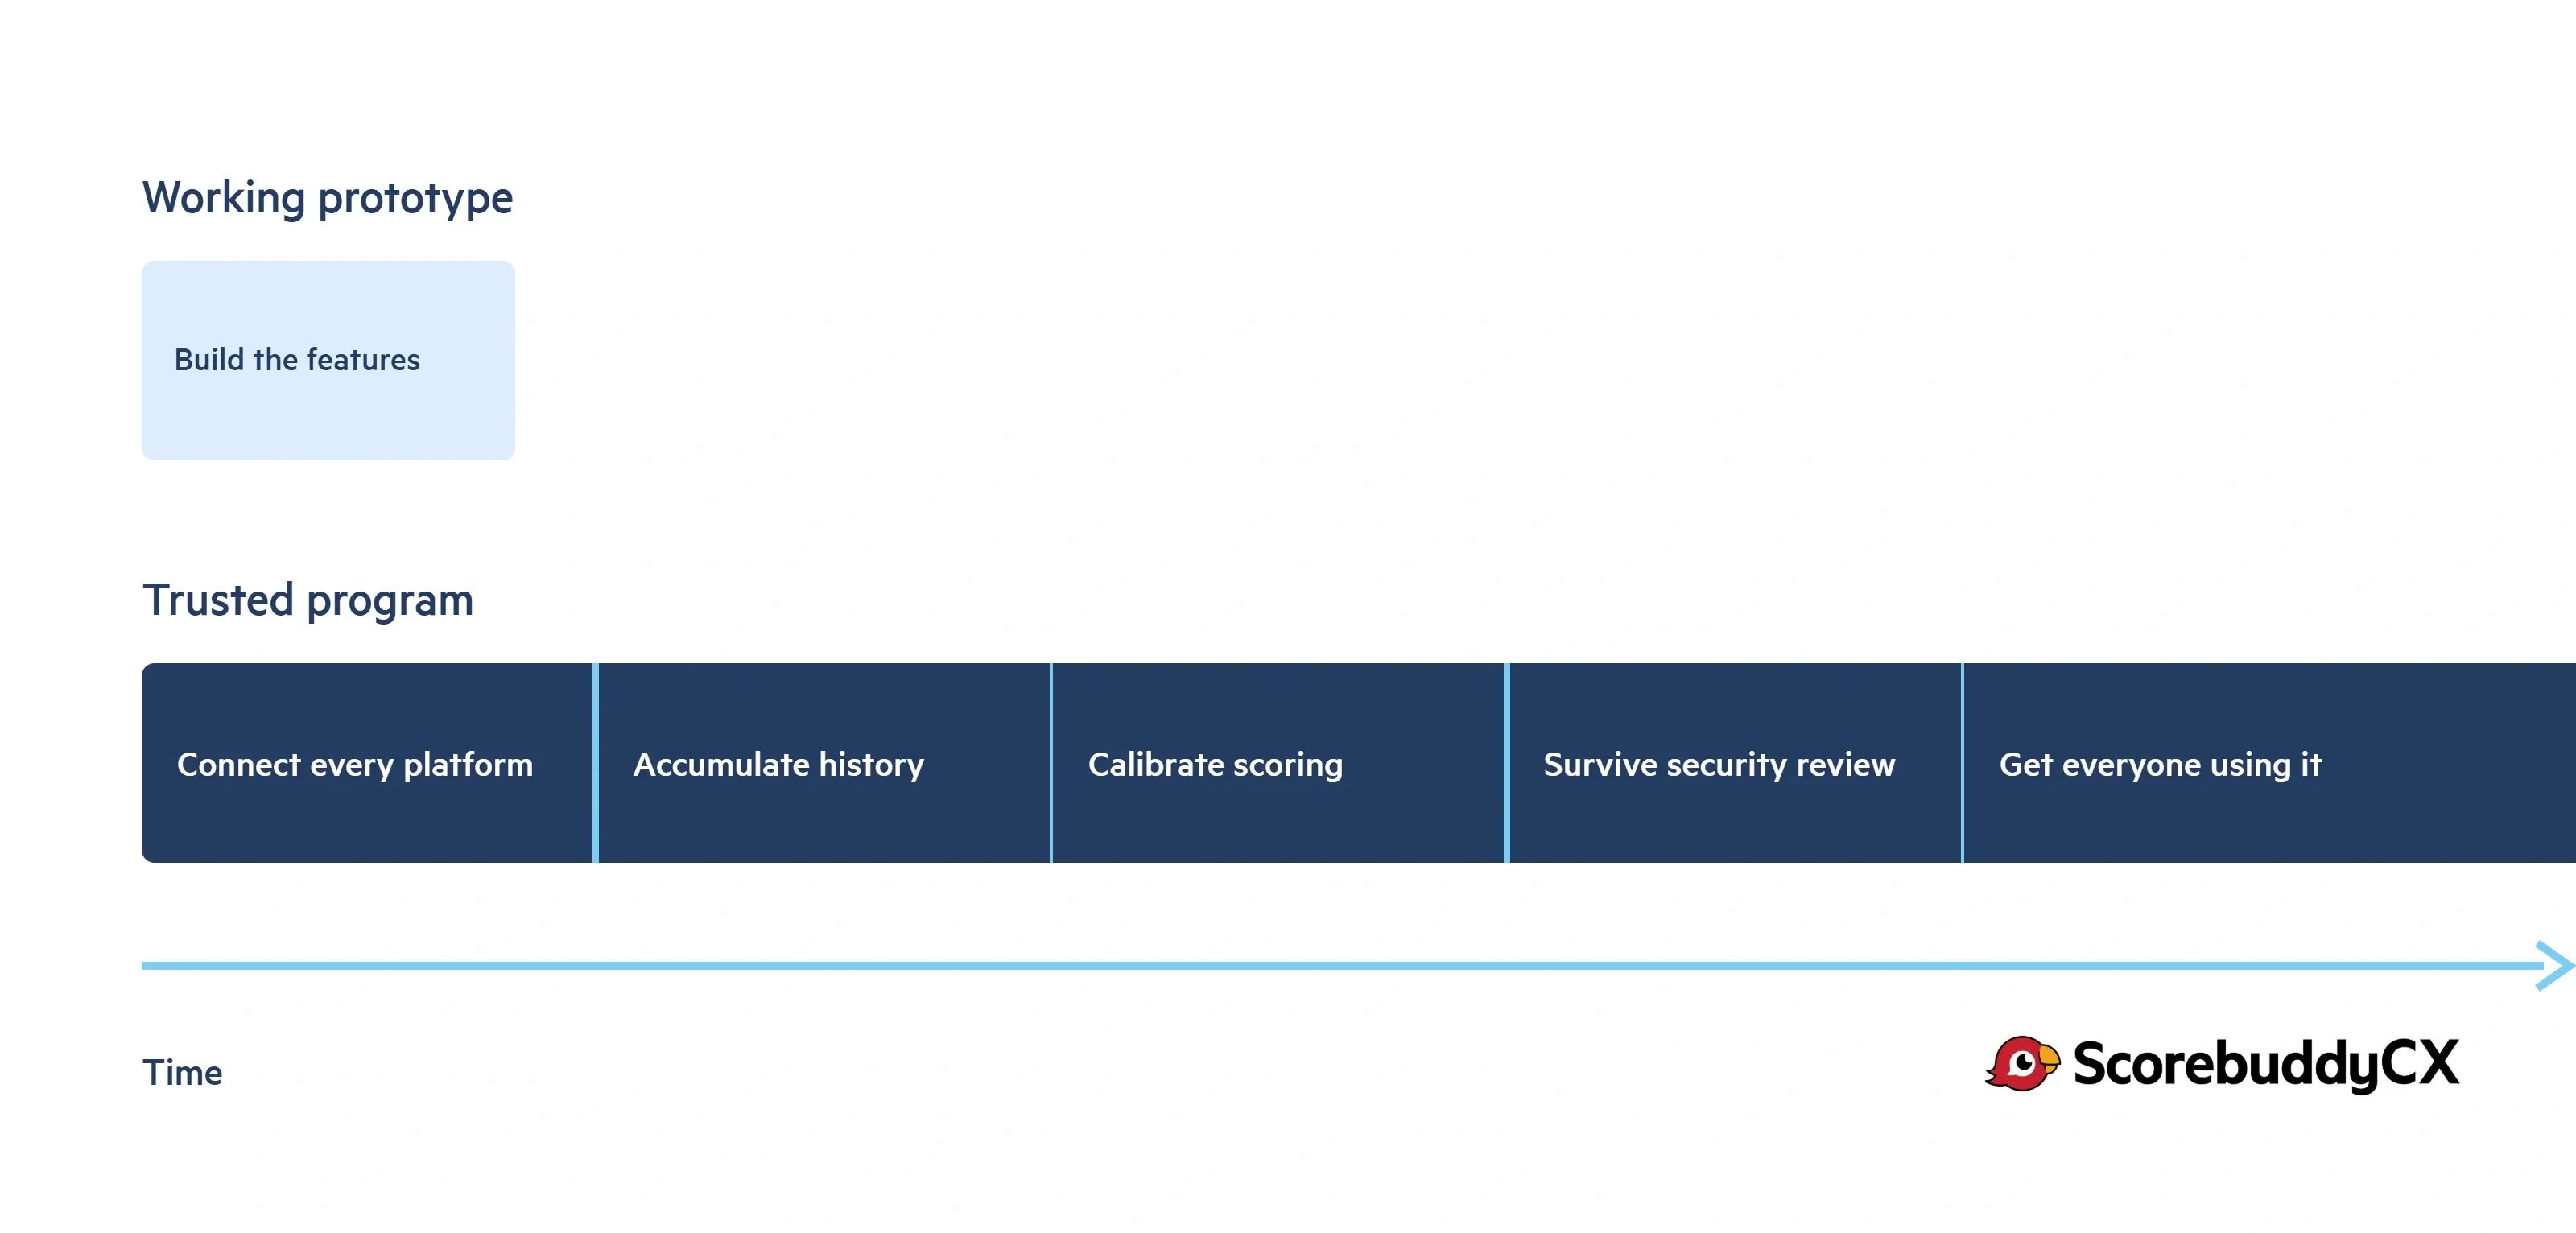
The speed claim also hides a measurement sleight of hand. Time to a working prototype and time to a trusted quality program are very different numbers, and they are not within an order of magnitude of each other. The first is just days, yes, but the second is a different story.
The second is however long it takes to connect every platform, accumulate enough history for a trend to mean anything, calibrate the scoring against your human graders, survive a security review, get four different audiences to actually use the thing... You get the point.
And that's what a business actually needs. So when the estimate says a weekend, the useful question is which of the two milestones is being quoted as taking "a weekend".
The score has to be believed
This is where I would push hardest, because it's specific to quality assurance and it is where internal builds most often fail invisibly.
Automated scoring is a calibration discipline. One model call gets you a number; the discipline is what makes anyone believe it. You measure agreement against your human graders, then tune the rubric wording until it produces consistent results. Someone watches for drift as models, products, and customer language change underneath you. And when an agent disputes a score, there is a route for it, because they will dispute one, and they will be right often enough that you need it.
A quality program lives or dies on whether people trust the number. A tool that produces confident, uncalibrated scores will cost you the credibility of the quality function. The bill arrives slowly, and you only find out two performance cycles later when nobody is using the scores for anything that matters.
The tool gets built for the people in the room
Four audiences depend on a quality program and they want different things: the evaluators who score, the team leads who coach from the results, the agents who are scored, and the executive who reads one summary a month and probably never opens anything else.
When you build your own quality assurance software it's almost always designed with real care for the first group, because they are the ones in the room when it is specified, and so it's merely tolerated by the other three.
Adoption dies in small increments. A team lead goes back to a spreadsheet because the report they need takes six clicks, and an agent stops reading their scores because there is no way to challenge one. By the time either of those is visible, the tool is a year old and nobody wants to be the person who says so.
Data gravity is the part a demo can't show you
Every prototype works beautifully on 10,000 interactions.
The interesting failures start somewhere north of 100 million, and they are all deeply unglamorous. Index strategy. Query plans that were fine last quarter. Deduplication when a source system replays records. Retention windows. The working set that no longer fits in memory, so search latency triples and nobody can say why.
None of that appears in a demo, because a demo has no history. And a quality program is almost entirely history. Nobody is really asking for a scoring tool. They want to know whether coaching is working, which teams are drifting, which agents need help this month, and whether the rubric change made anything better.
Every one of those answers comes out of reporting, benchmarking, and enough data behind them for trends to become visible. Which is why the history is the deliverable, and why a tool that scores perfectly from day one still might not have anything useful to say for two quarters. The moment it does have something to say is the moment those queries start to get expensive.
What about all those integrations?
Your contact center data doesn't sit in one system. It sits in Genesys, or Zendesk, or Freshdesk, or Five9, or Talkdesk, or 8x8, or Salesforce, and realistically in several of them at once, plus whatever you sign up for next year.
Each of those platforms has its own authentication model, pagination behavior, rate limits, and opinion about what an incremental export means. An AI agent will write you an excellent connector against today's API documentation. But what about tomorrow?
What that agent will not do is notice, at 03:00 on a Sunday, that a vendor changed a field from a string to an array without telling anyone and stopped your ingestion dead. It will not read the deprecation notice buried in a changelog. It will not care that your QA leads are running a calibration session on Monday morning with three days of missing data.
The reality is that someone has to own that. Forever. Across every platform you touch.
We own it, and the reason we keep broadening the set is not completeness for its own sake. It's that quality intelligence gets more useful the more of the customer journey you can see at once. One channel tells you how an agent performed. Several, joined up, start telling you where the process itself is failing them, and what the organization should change as a result.
Sidebar: you already have obligations here
The EU AI Act classifies a system that monitors and evaluates how people perform at work as high-risk. This is not a problem arriving at some future date. If you are running automated scoring over your agents today, you are already inside the scope of it, and so is your vendor.
Build it yourself and you become its provider. That is the heavier of the two roles, and it brings the full set: a risk management system, data governance, technical documentation, logging, human oversight design, conformity assessment, and registration. Alongside the things you already had, which are ISO 27001, SOC 2 and GDPR.
Buy it and the provider obligations sit with your vendor, but you are still the deployer, and that role is not empty. You remain accountable for assigning human oversight to people competent to exercise it, for the relevance of the input data you feed it, for monitoring and for retaining logs, and for informing workers and their representatives before the system is put into use. Depending on your sector you may also owe a fundamental rights impact assessment.
I'd rather say that plainly than let you discover it later. Buying does not make the obligation disappear. It removes the larger half of it, and it gives you a counterparty who has already been through the assessment, holds the certifications, and has an auditor's phone number.
Because you cannot prompt your way to a certification. A certification is evidence, gathered over time, held by an accountable owner: a risk register, data protection impact assessments, AI impact assessments, a sub-processor list, penetration test results, data residency decisions, and a breach process someone has rehearsed. An AI agent can draft your retention policy in a minute. It cannot sign it, own it, or work through the audit with your auditor.
What year two looks like when you build your own QA tool
One of our customers went and did it. Their QA team ran quality across a high-volume dispatch operation in the US, the company was pushing hard on AI, and building their own scoring tool looked like the obvious move. They were right that they could. They researched it, refined the requirements, tested the output, and went live with something that worked.
Changing a scorecard meant raising it with IT, which is a fair trade in a pilot and a bottleneck in a live program. Coverage never came back to the level the team had been working at.
A category of tracking nobody had scoped turned out to matter more than anyone expected. They described what they had built as good, but not good enough.
Individually none of it would sink a quality function. Over two years it added up. There was no failed audit and no moment of crisis, only a sense each quarter that they were falling further behind. Reporting was the largest gap of the lot.
Their infrastructure bill was never the deciding factor. What they could not get back was flexibility, coverage, and the reporting the program depended on.
Acting on it took another 12 months after they knew, because reversing a decision like that takes time inside an organization. They are now a customer again. Nothing that went wrong was an engineering problem.
None of what they ran into was unusual, either. That's the uncomfortable part. Every one of those failures is one we have already had, years earlier, and fixed once on behalf of everybody. Knowing which of them matter, and in what order they arrive, isn't something you can specify up front. It's the thing you only have after you've run quality programs for long enough to see the same shapes repeat.
When you should absolutely build it yourself
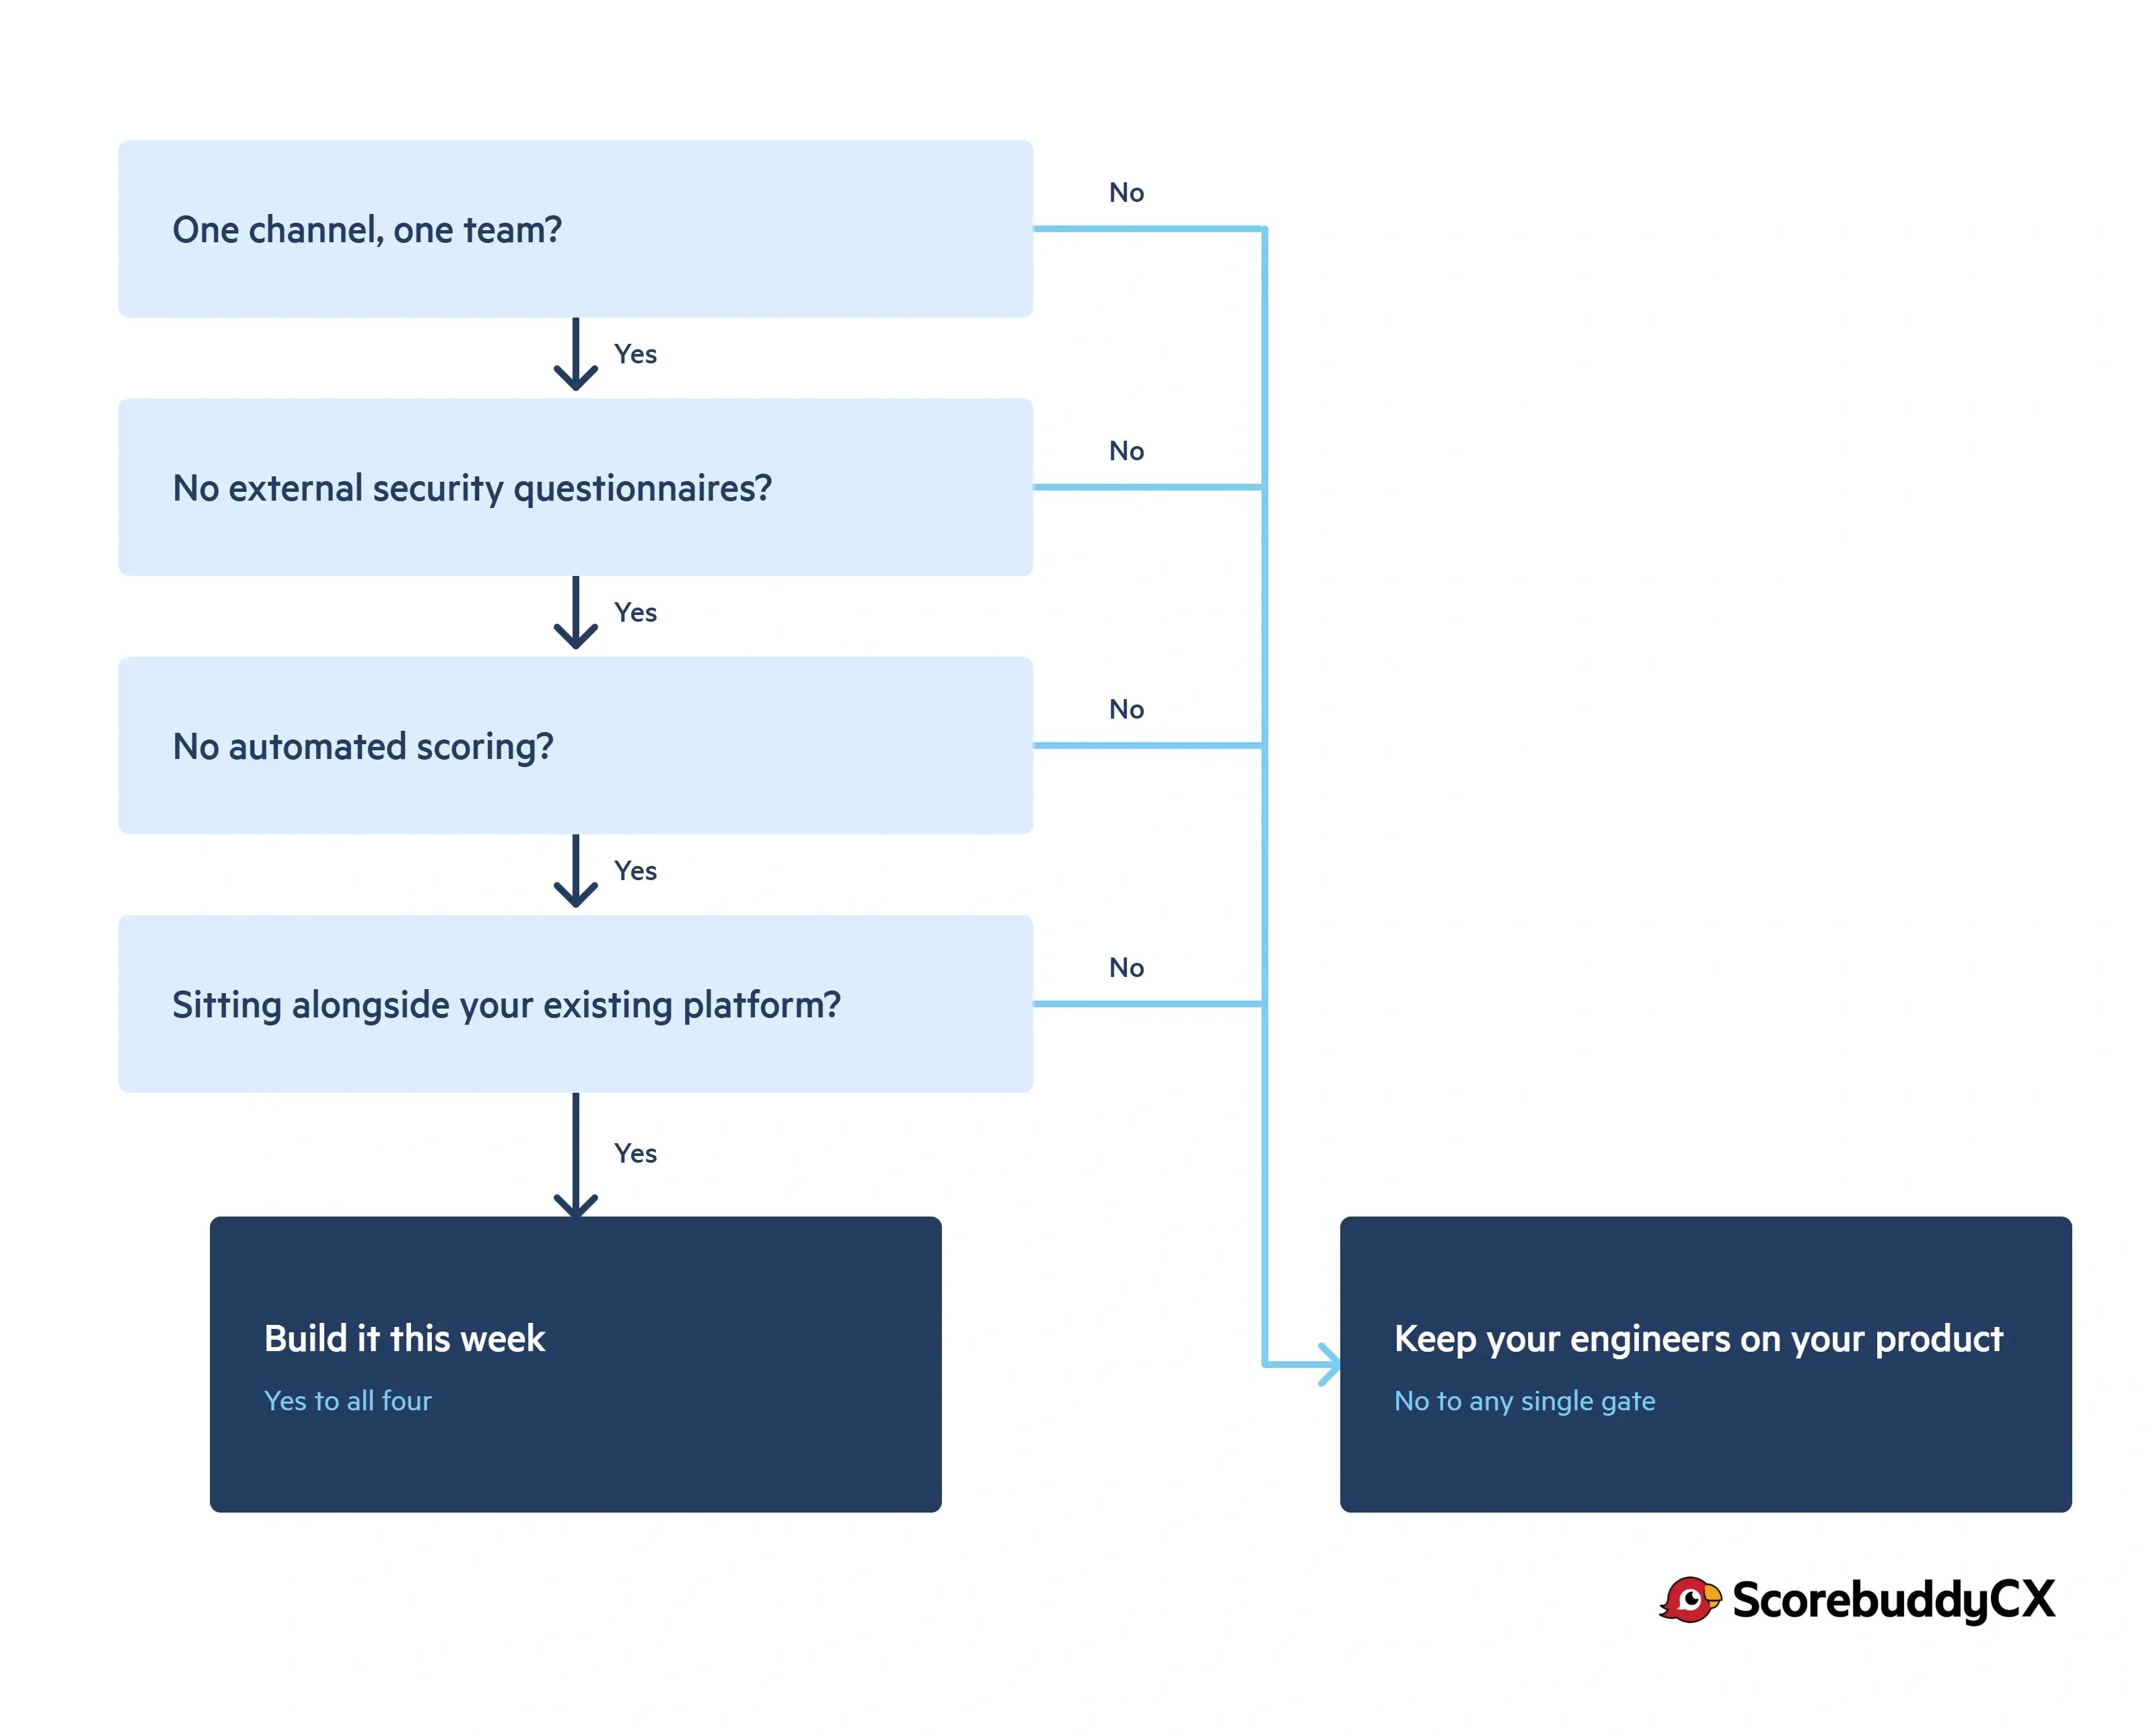
I would be doing you a disservice if I pretended the answer was always buy. Build your own QA software with an AI agent when:
- You have one channel, one team, and no plans for a second.
- Nobody outside your own company will ever ask you for a security questionnaire.
- There is no automated scoring, so there is nothing to calibrate and nothing to defend.
- The job ends when the question is answered. Keep the output, throw away the code.
- It sits alongside a platform you already have, as glue, rather than replacing it.
Those are real, viable cases and they are more common than vendors like to admit. If you are in one of them, go and build the thing this week. You'll probably enjoy it.
So what is the actual trade off?
Everything above comes down to a single choice, but it's not a technical one.
The cost of building is not confined to the build. It is roughly half an engineer to an engineer, indefinitely, plus infrastructure, plus on-call, plus a support queue your own colleagues now file tickets into, plus a backlog you owe them.
And it concentrates in one person. The engineer who prompted it into existence moves to another team, or leaves. Nobody else read the code closely, because nobody ever had to. There was no review, no design document, and no second opinion, because the whole appeal was that none of that was necessary. Code that nobody reviewed is inherited debt with no author.
Then one day that engineer is no longer working on the thing your company competes on.
That's the obligation we took on, and we've been carrying it since 2012. It's why we know what good looks like in a quality program, and why we can tell you which problems are worth your attention before you meet them. We score conversations at scale, and we turn what's in them into coaching, training, and the reporting the rest of the business keeps asking QA for.
You can absolutely build it in a weekend. The question worth asking is what year two looks like, and who is left responsible.
If you'd rather inherit that than build it, see what it looks like in practice.